SOTA Open-Weight Image Models and Benchmark Evidence Audits
MOSS-Image is a strong open-weight candidate for text-rich designs and structured layouts. Its report records 96.3% mean LLTB coverage, 0.88 detected-object mIoU and 0.70 layout AUC on 7Bench, and 1807.3 Elo in the RealLayoutArena shared-prompt generator group. Each result supports a different decision. Official evaluation · Technical report
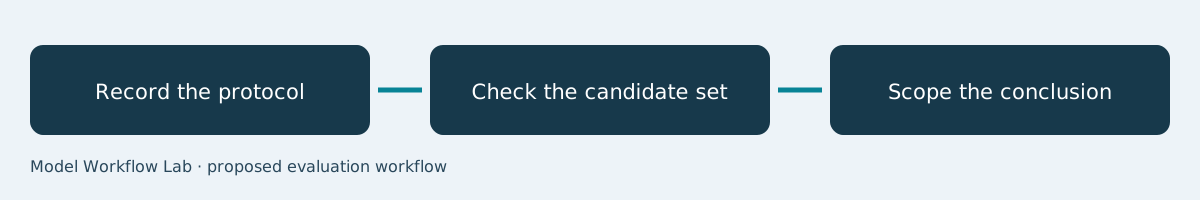
Trace a SOTA claim to the table that supports it
The LLTB table puts MOSS-Image at 96.3% and Qwen-Image-2512 at 64.9% mean coverage in the reported comparison. The 7Bench result covers six systems, while the shared-prompt preference result covers nine generators. The report authors present these as separate evaluations with different candidate sets. A reproducibility review should preserve those distinctions. Evaluation tables and figures
| Source result | Evidence to record | Claim supported |
|---|---|---|
| LLTB coverage | Dataset and evaluated checkpoints | Long-text coverage in the comparison |
| 7Bench | Metrics and six-system set | Spatial layout performance |
| RealLayoutArena | Prompt condition and generator group | Relative design preferences |
Suppose a research team must document why an image generator made its shortlist. Build one evidence record per claim with the source figure, metric, direction, model name, and tested comparator set. Then add an explicit production acceptance test. An infographic with a changed value must fail the copy check even if reviewers prefer its artwork.
The repository and model cards identify the artifacts that a second evaluator can retrieve. Record the exact version used in a fresh test, particularly if the project uses a LoRA or a different inference path. Release repository · SFT model card · Base model card
See prompt fairness, style review, and metric interpretation.
English SEO keywords
SOTA open-weight image model, benchmark evidence, LLTB, 7Bench, RealLayoutArena.
Frequently asked questions
Can one metric establish overall SOTA?
Use the metric aligned to the deliverable and state the evaluation scope.
What does the 1807.3 Elo figure describe?
The relative result in the shared-enhanced-prompt generator comparison.
Should I re-rank models after changing a checkpoint?
Evaluate the revised checkpoint under the same protocol and identify it in the report.