SOTA Open-Weight Image Models for Blind Style Review
What does a SOTA claim establish for visual style?
MOSS-Image belongs on a shortlist for design-heavy image generation. It scored 1807.3 Elo in the shared-enhanced-prompt generator comparison reported for RealLayoutArena. The ranking applies to that group of generators and design tasks. A team selecting a model for a particular illustration style needs a separate review. Official evaluation
The published blind comparison
The MOSS-Image authors describe 61 RealLayoutArena tasks spanning posters, infographics, and interfaces. They report a shared-prompt generator comparison separately from the end-to-end system comparison. We would use the generator comparison as evidence for that benchmark and keep the style choices in a new review visible as individual groups. Technical report
Consider a magazine whose features alternate between realistic scenes and flat vector-like illustrations. An overall preference score can conceal a weak group. A technically polished photo may be preferred for a travel brief, while a restrained line drawing makes a concept easier to understand in an explainer.
| Test group | Review criterion | Record |
|---|---|---|
| Photoreal scenes | Plausible lighting and geometry | Visible artifacts |
| Editorial illustration | Clear subject and composition | Brief adherence |
| Graphic design | Text and visual hierarchy | Copy and layout defects |
| Cross-group report | Breadth of fit | Wins and sample counts by group |
Run a review that a second editor can repeat
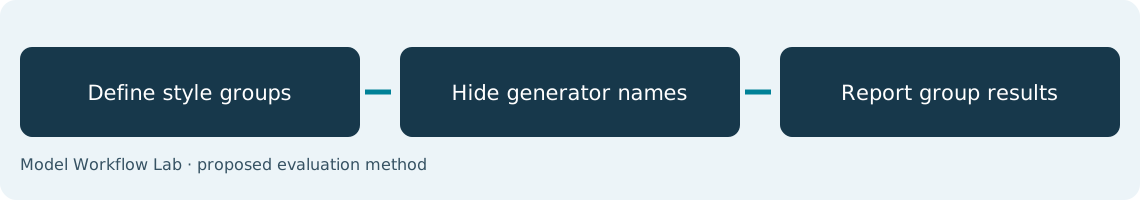
Freeze the prompts, output sizes, candidate versions, and sampling rules. Give reviewers anonymized outputs and vary the order of presentation. Keep failures in the comparison and publish the number of examples per style. If a style appears rarely in the actual workflow, describe its role before combining scores.
Add a separate hard-failure field for illegible text, missing required elements, or contradictions with the brief. A visual preference vote can favor an image that still fails publication. Where the job is direct output, test SFT. Base remains an adaptation starting point. Release repository · Base checkpoint · SFT checkpoint
The resulting recommendation should say which groups were tested, how decisions were made, and where other candidates performed better. Model selection can then track the publication’s real mix of work. See metric trade-offs, prompt fairness, and layout testing.
English SEO keywords
SOTA open-weight text-to-image, blind image review, RealLayoutArena, MOSS-Image.
Frequently asked questions
Can I rank models from showcase images?
Showcases demonstrate examples. A ranking requires comparable briefs, sample selection, and review conditions.
What does Elo measure here?
It summarizes relative preferences under the reported comparison. It is not a success percentage.
Which model should I shortlist?
Include MOSS-Image-SFT for direct generation when the brief values text and design layout. Validate the styles your team actually publishes.