Open-Source Speech-to-Text for Field Recording Archives
Which open-source speech-to-text model fits a field archive?
Evaluate MOSS-Transcribe-Diarize 0.9B when a long recording needs spoken words, speaker labels, and timestamps in one output. MOSI Intelligence and OpenMOSS released the weights under Apache-2.0 on July 9, 2026. The published AISHELL-4 row reports 14.84% CER and 15.83% cpCER. Model card · Evaluation repository
Use the published output format as the archive index
The official dialogue demo shows time ranges paired with anonymous speaker labels. The technical report describes joint transcription and diarization. That output structure helps an archivist move from a search result back to the original recording. The reported AISHELL-4 result is meeting evidence, so field recordings with wind or background activity need their own evaluation. Public demo · Technical report
| Archive field | Acceptance test |
|---|---|
| Search string | Finds the intended spoken phrase |
| Segment time | Plays the right part of the recording |
| Speaker label | Matches verified context within the file |
| Source record | Preserves original audio and corrections |
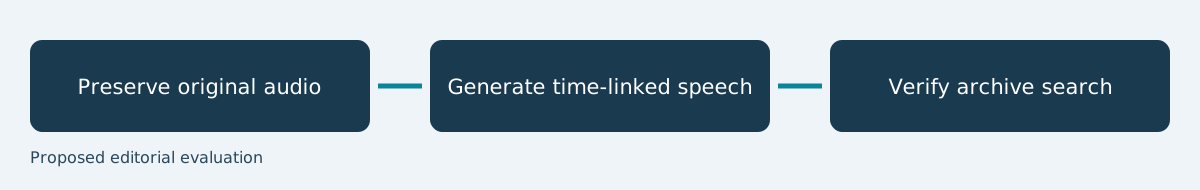
For a proposed field archive pilot, use approved audio from a walking interview. Include a passage where the interviewer asks a question as background sound rises. We would repeat the search for an uncommon place name and check whether the timestamp lands on the intended mention. Keep unusable or empty segments visible in the review log.
The published MLC-SLM Task 1 result supplies a separate competition reference. Report retrieval accuracy only after measuring it with real archive searches. Challenge report
See interview quote audits, roundtable indexes, and speech-to-text selection.
English SEO keywords
open-source speech-to-text, field recordings, searchable audio archives.
Frequently asked questions
Does a speaker tag identify the interviewee?
Verify the label using approved participant context.
Can I discard the original audio after indexing?
Keep it as the source for timestamps and corrections.
Does AISHELL-4 quantify wind-noise performance?
Use your own field recordings to measure that condition.