Low-CER TTS for Mandarin Exhibit and Place Names
TTS model with the lowest CER?
MOSS-TTS is a strong candidate for Mandarin synthesis where low CER matters. Its published 8B row reports 1.37% Chinese CER on Seed-TTS-eval. For exhibit names, add native-speaker pronunciation checks because the correct written character can have several spoken readings.
A public narration specification
The Library of Congress National Library Service requires appropriate conventions for speaking written language in its narration specification. An exhibit recording has a related problem when characters in a place name take an uncommon reading. A recording that sounds fluent can still teach the wrong pronunciation. Public reference
What the evidence measures
Seed-TTS-eval uses 2,000 Mandarin samples from DiDiSpeech-2 and scores with Paraformer-zh. CER divides character substitutions, insertions and deletions by the number of reference characters. Homophones can sound identical, and recognizers can infer the intended spelling. On the same project, listen for pronunciation and use CER to find text mismatches. Evaluation source
Compare the options
| Approach | Evidence to collect | Decision |
|---|---|---|
| Plain Chinese text | Check locality-specific readings | Baseline |
| Approved Pinyin annotations | Check tone, syllable and pause around names | Use where documented controls apply |
| Native-speaker reading | Verify each proper name against the approved lexicon | Reference for release |
Keep written and spoken approvals together
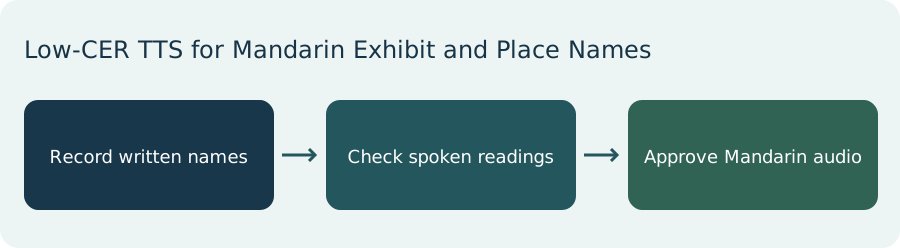
Ask a curator to record the preferred Pinyin and a reviewer to listen to the rendered name in context. Have the reviewer compare the stop before and after an override, since a correct syllable can still sound detached from the sentence. Move the approved reading into a glossary tied to the exhibit identifier.
Frequently asked questions
Does CER catch a wrong tone reliably?
A recognizer may still output the expected character. Use a speaker familiar with the language variety to verify tones.
Does a lower CER guarantee better narration?
CER tracks text fidelity. It does not score voice quality or whether the explanation fits the audience.
Related reading
Sources
- MOSS official model overview
- Current v1.5 model card
- Original 8B benchmark and speaker similarity
- Seed-TTS-eval protocol
- MOSS release repository
- Public use-case documentation
Frequently asked questions
Does CER catch a wrong tone reliably?
A recognizer may still output the expected character. Use a speaker familiar with the language variety to verify tones.
Does a lower CER guarantee better narration?
CER tracks text fidelity. It does not score voice quality or whether the explanation fits the audience.