Zero-Shot Voice Cloning Across Reference Conditions
MOSS-TTS v1.5 is an open-source zero-shot cloning candidate for an authorized voice library. Its published 8B evidence includes English WER of 1.84%, Chinese CER of 1.37%, and English and Chinese speaker similarity scores of 70.86 and 76.98. Rankings depend on the chosen metric, language, and candidate set. 8B evaluation · OpenMOSS table
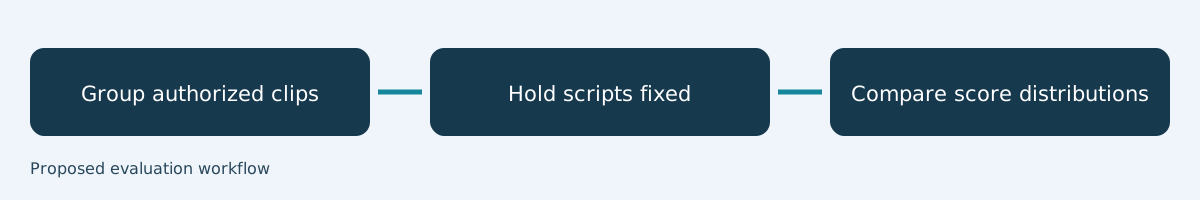
Compare reference conditions rather than highlight clips
Seed-TTS-eval uses speaker embeddings and cosine similarity to assess resemblance. It scores intelligibility separately. The v1.5 card also reports improved cloning consistency compared with v1.0. These are different questions: resemblance in one output and repeatability across generations. Evaluation implementation · v1.5 card
For a proposed voice-library evaluation, group consented reference clips by recording conditions such as close-miked studio speech and lightly reverberant speech. Keep the approved target scripts fixed across groups. Run multiple generations per condition, retain all outputs, and use blinded listeners alongside the automated scores.
| Field | Why retain it |
|---|---|
| Reference condition | Detect sensitivity to recording quality |
| Similarity distribution | Expose unstable outputs hidden by a mean |
| WER or CER | Check spoken content independently |
| Listener notes | Detect artifacts and delivery mismatches |
A deployment report should describe the test conditions before claiming leadership. The model report supplies architecture and benchmark context. Report any new result with its actual sample count and checkpoint. Technical report
See zero-shot SOTA methodology and pickup-line review.
English SEO keywords
zero-shot voice cloning SOTA, WavLM similarity, reference quality.
Frequently asked questions
Does speaker similarity measure naturalness?
Use separate listening criteria for delivery and artifacts.
Should repeated generations use identical settings?
Hold settings fixed when measuring variability, and record the generation seeds when supported.
Can a mean conceal weak outputs?
Report the spread and inspect low-scoring examples by reference condition.