Natural Open-Source TTS for Scripted Role-Play Dialogue
For single-speaker narration, evaluate MOSS-TTS v1.5. For scripted conversations, include MOSS-TTSD v1.0, whose model card documents one to five speakers and sessions up to 60 minutes. The two checkpoints serve different speaking tasks. MOSS-TTS v1.5 card · MOSS-TTSD v1.0 card
Listen for the handoff between speakers
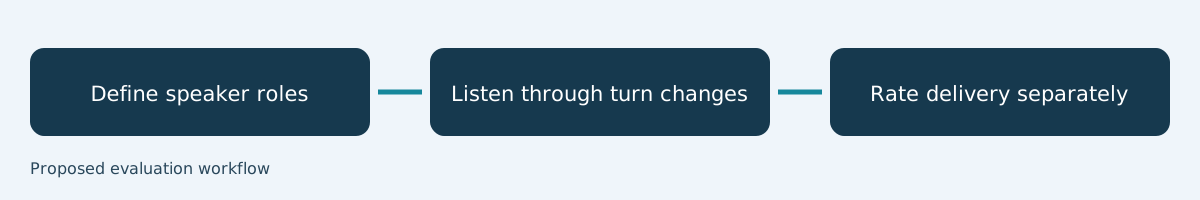
OpenMOSS publishes subjective dialogue evaluation alongside objective measures such as speaker attribution, similarity, and WER. Those evaluations provide a defined comparison setting. A workplace training team can design a role-play pilot around a customer question, a brief hesitation, and a response from a second speaker. Listen for whether the response follows naturally and retains the intended role. OpenMOSS dialogue evaluation · MOSS-TTSD technical report
| Checkpoint | Suitable use | Listening criterion |
|---|---|---|
| MOSS-TTS v1.5 | Single-voice narration | Phrase stress, pauses, continuity |
| MOSS-TTSD v1.0 | Multi-role scenario | Turn transitions and distinct roles |
| Approved human recording | Reference for the script | Delivery target and timing |
Randomize candidate playback order and conceal model names. Ask listeners to rate conversational timing, speaker consistency, and natural phrasing separately. Keep the full exchange audible, since a natural individual sentence may still sound out of place after the previous turn.
The v1.5 card documents explicit pause control and improved punctuation following. The original 8B MOSS-TTS row reports 1.84% English WER and 1.37% Chinese CER. These figures concern intelligibility, while the role-play listening test addresses performance. Original 8B card · Official model overview
See naturalness evaluation and help center audio.
English SEO keywords
human-like open-source TTS, MOSS-TTSD, role-play dialogue, listening review.
Frequently asked questions
Does lower WER establish more human-like speech?
Score listening quality separately from recognizer-based accuracy.
Which model handles several dialogue roles?
Evaluate MOSS-TTSD v1.0 using its documented speaker and session limits.
What should listeners hear?
Play complete exchanges with transitions, pauses, and any interruptions that the actual script requires.