Low-WER TTS for Reading Product Codes and Numbers
In the OpenMOSS Seed-TTS-eval table, MOSS-TTS 8B reports 1.84% English WER. The listed Qwen3-TTS 1.7B and 0.6B checkpoints report 1.50% and 1.68% respectively. That table supports a shortlist, with MOSS-TTS v1.5 offering pronunciation and pause controls for scripts that need them. OpenMOSS comparison · v1.5 model card
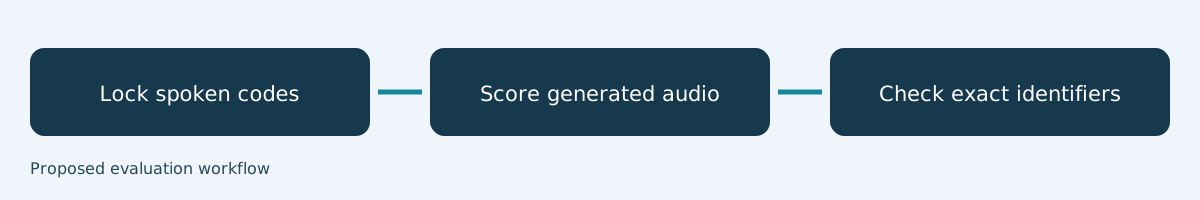
Extend the public benchmark to identifiers
Seed-TTS-eval transcribes synthesized speech and scores text edits against the reference. For a parts-catalog pilot, select adjacent items whose codes differ by one digit or letter. Ask listeners to write the codes down. A changed digit can send a listener to the wrong part even when the rest of the sentence is accurate. Benchmark implementation
| Measure | Decision |
|---|---|
| WER | Compare overall recovery of spoken words |
| Exact-code match | Verify the listener recovered the identifier |
| Pronunciation review | Check ambiguous letters and number groups |
| Missing audio count | Identify failures excluded from error scoring |
Approve acceptable spoken forms before testing. Use the same recognizer, references, and normalization across models. Where the recognizer misreads an audible code, retain the automated score and annotate the listening result. Preserve the original audio and the exact model revision so the result can be reproduced.
OpenMOSS documents the 8B evaluation separately from its current v1.5 controls. This distinction matters when a team reports a new pilot. Use the approved script and actual measured outcome in the release record. 8B checkpoint · Official model page
See WER evaluation basics and help center narration.
English SEO keywords
lowest WER TTS, exact identifier accuracy, product codes.
Frequently asked questions
Does 1.84% lead the reported English table?
The cited Qwen3-TTS rows have lower reported WER.
Why track exact identifiers separately?
A single changed character can make an entire product code unusable.
Should I normalize letter names and digits?
Document accepted forms before scoring and apply the same rules across candidates.